The problem
CKB is a global community where Chinese and English are the two main languages, and spoken communication across them is hard. Written communication is fine (AI translation handles documents well), but live discussion suffers. For this pain point we need good caption-style translation: English speech shows Chinese text, Chinese speech shows English text. Priorities: translation accuracy first, then low latency. Runs on cloud APIs or a MacBook Pro M4 Pro (24GB). (Don’t ask why it only has 24GB, that’s stupid of me when I bought the Macbook.  )
Solution landscape
| Approach | Examples | Quality ceiling | Latency | Cost per hour | Hardware needed |
|---|---|---|---|---|---|
| End-to-end interpretation API | Volcano LiveInterpret 2.0, Azure Live Interpreter | LLM (SOTA) | ~2.2s first text | Priced as AI interpretation; you pay for the unused TTS branch | Any laptop |
| ASR + MT cascade (this solution) | Seed-ASR 2.0 + Volcano MT LLM | LLM, glossary-enforced | <1s interim, ~0.5s refined after sentence end | ≈ ¥3.5/h ($0.49); ≈ ¥0.5/h ($0.07) on packs | Any laptop |
| Meeting-platform built-ins | Teams, Google Meet, Zoom translated captions | NMT/LLM | 2–4s | $10–20/user/mo subscription; some platforms lack glossary support | Any laptop |
| iFlytek 同传 LLM tier | iFlytek simultaneous interpretation | LLM | 2–4s | ¥40.8/h ($5.7), sold as ¥4080 ($570)/100h; no distinction between speakers, and the quality is poor. | Any laptop |
| Google self-built | Cloud STT Chirp + Cloud Translation | LLM | 2–4s | ≈ $1.2/h (¥8.5); mainland China needs network workarounds | Any laptop |
| Fully local models | SenseVoice + Whisper turbo + TranslateGemma (MLX) | Good, below cloud LLM | 2–4s | Free | Apple Silicon with ≥24GB RAM (36GB+ will be better) |
This solution
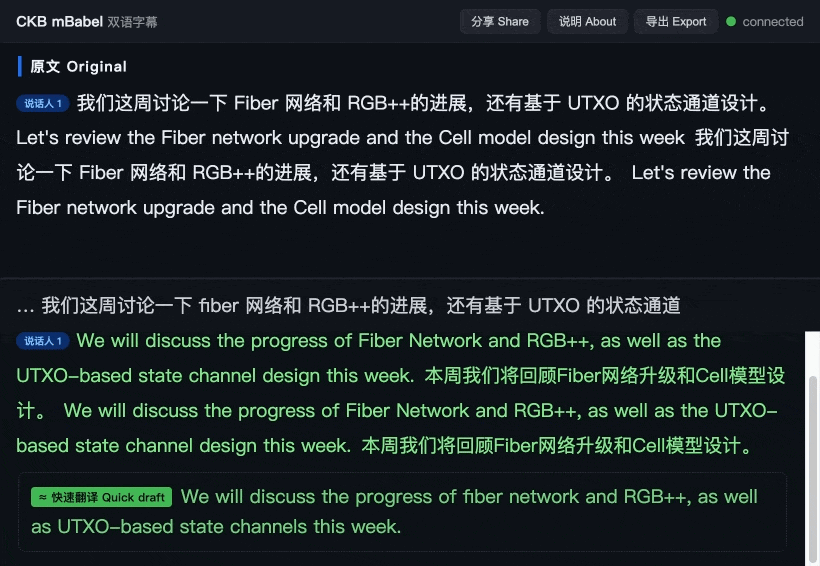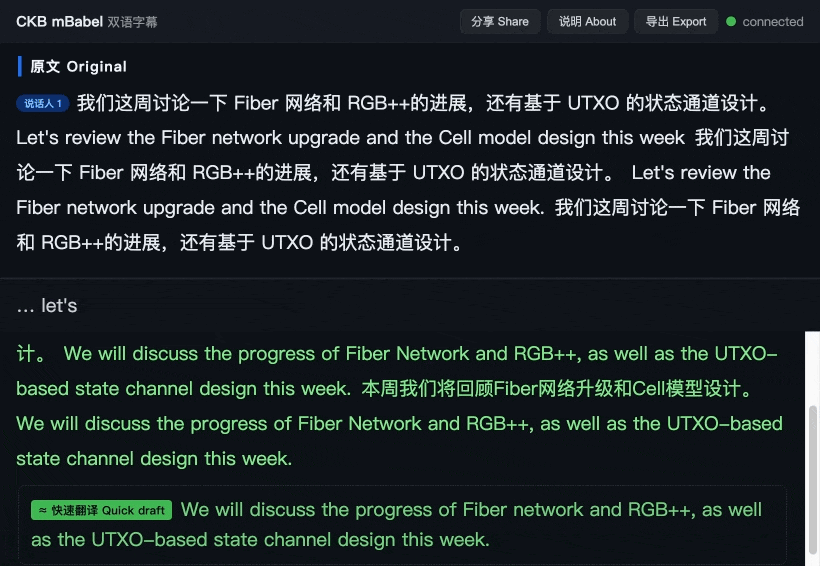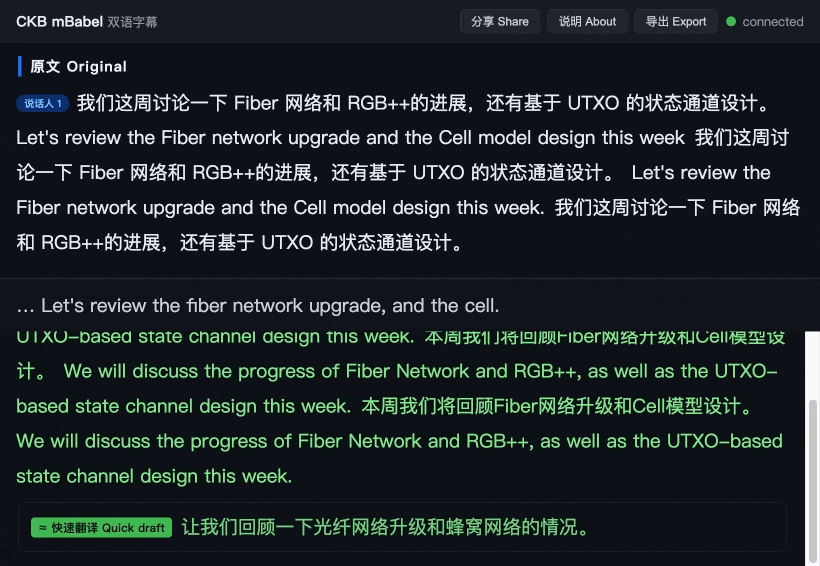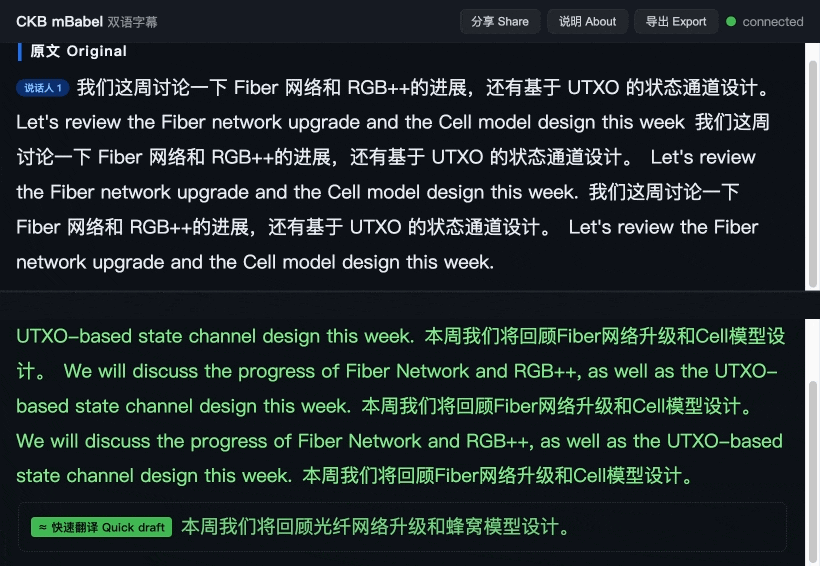
It’s ~12x cheaper than iFlytek’s LLM-tier simultaneous interpretation while running newer models, and ~2.5x cheaper than a self-assembled Google stack. One Volcengine speech console API key covers both recognition and translation:
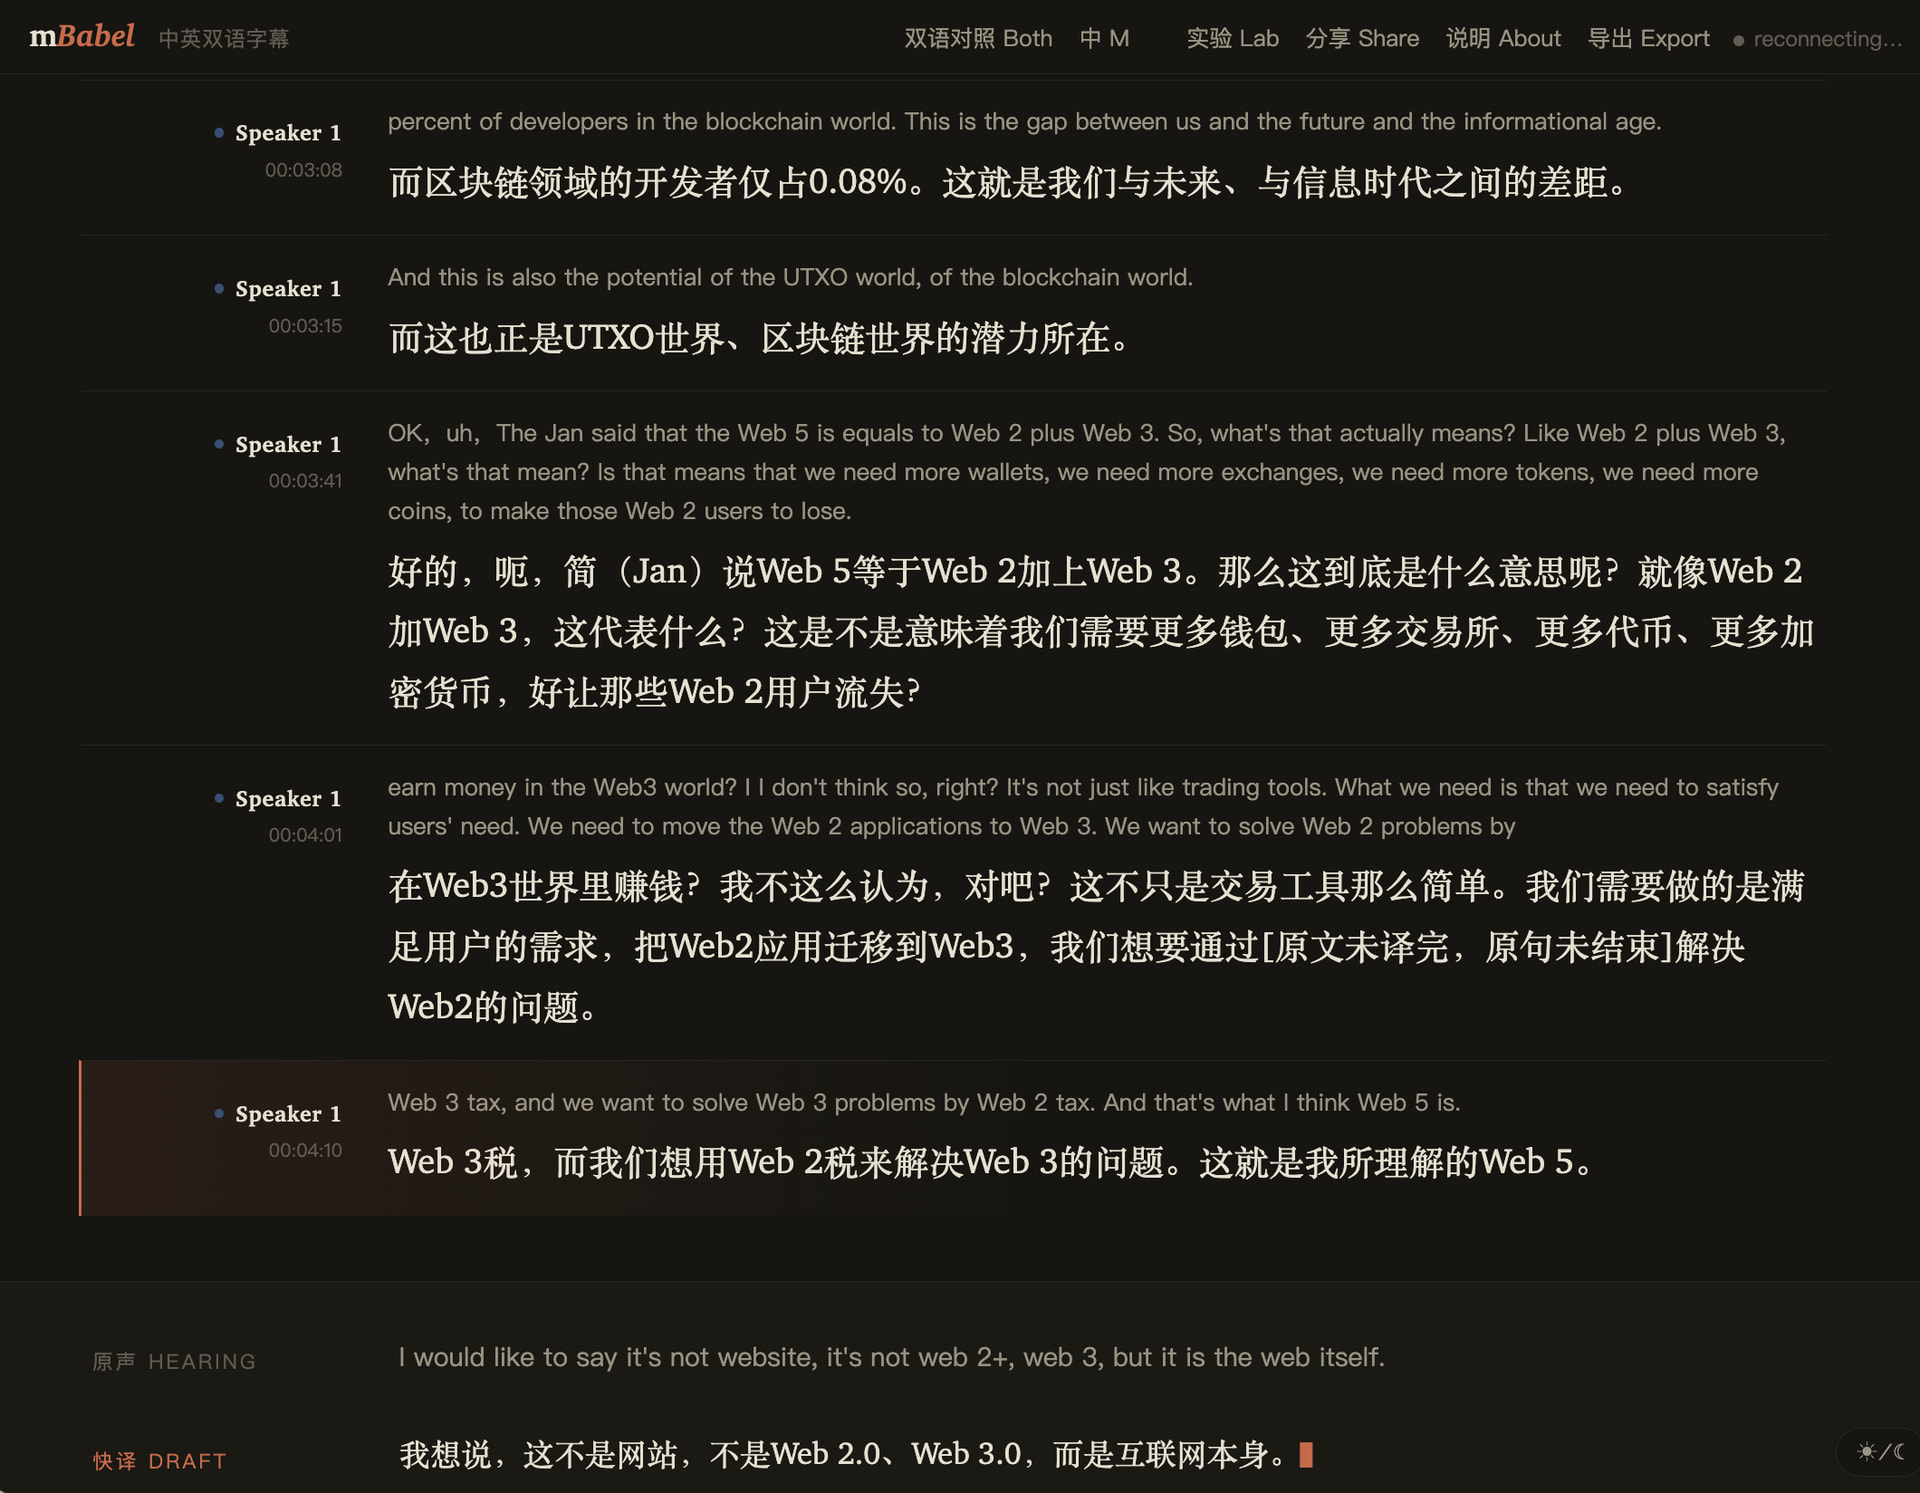
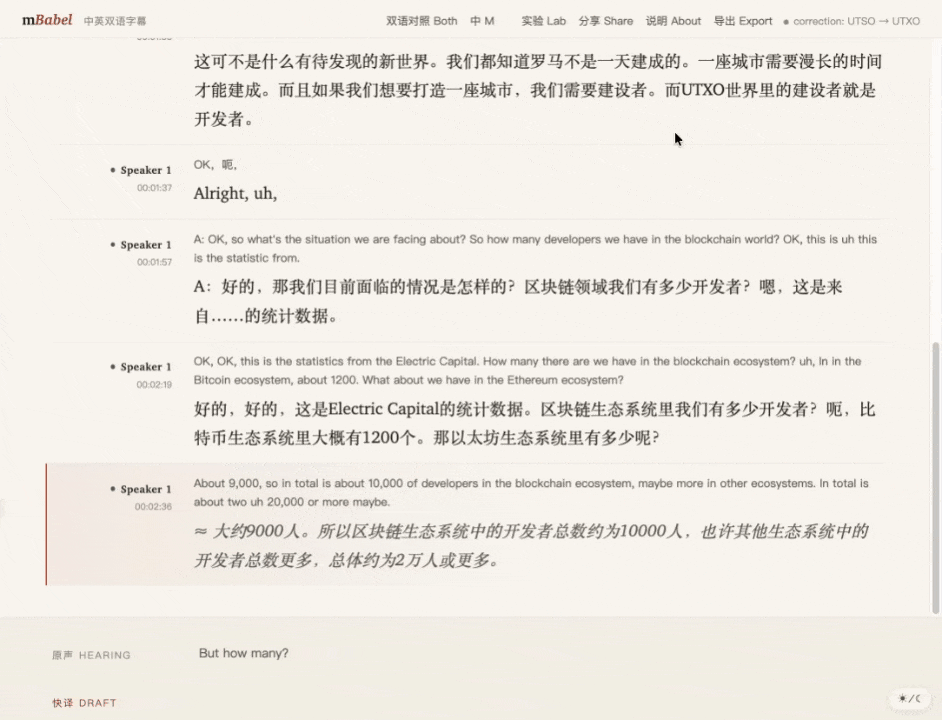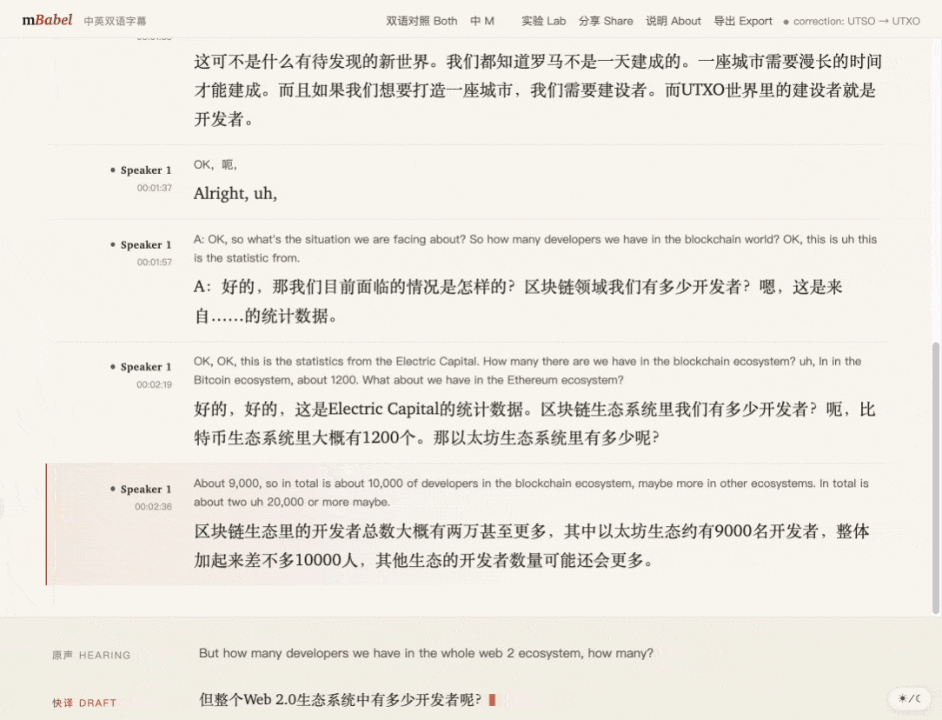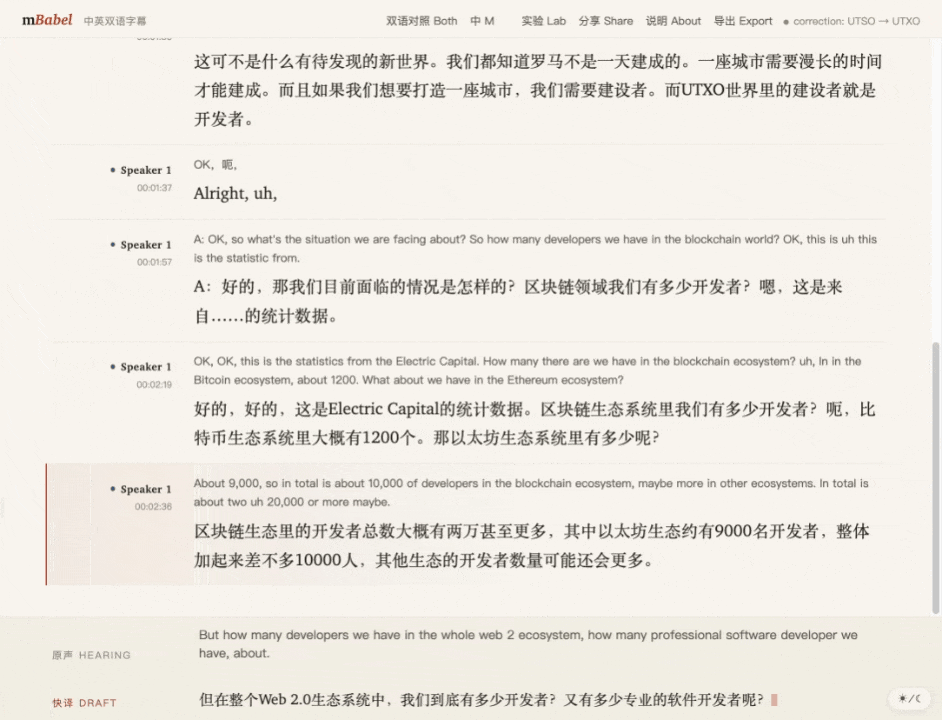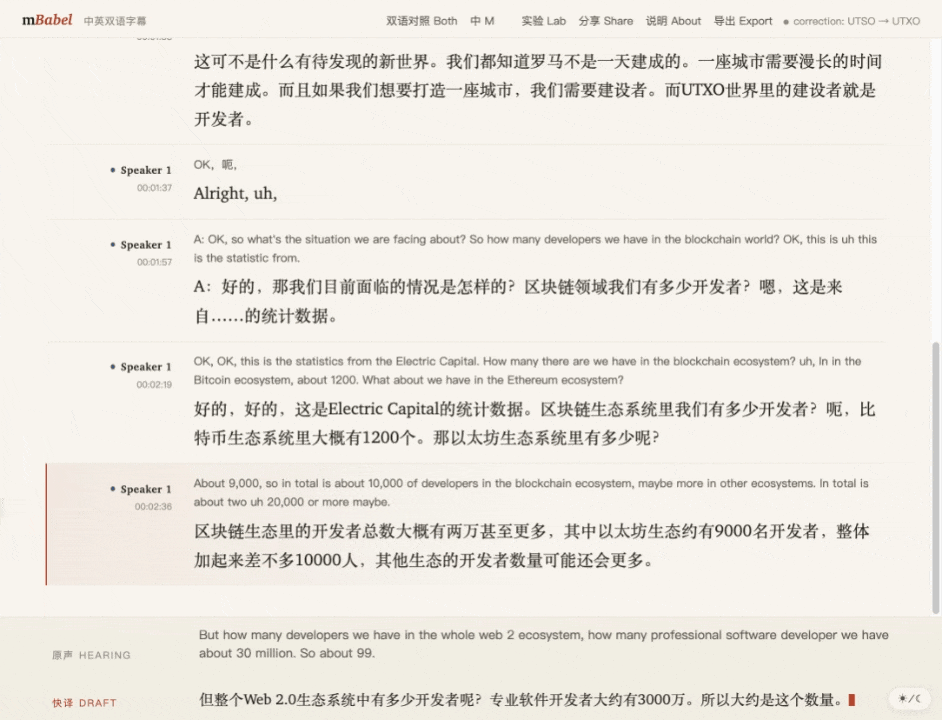
- Dual-direction captions in a browser page: Chinese speech → English, English speech → Chinese, code-switching handled per sentence.
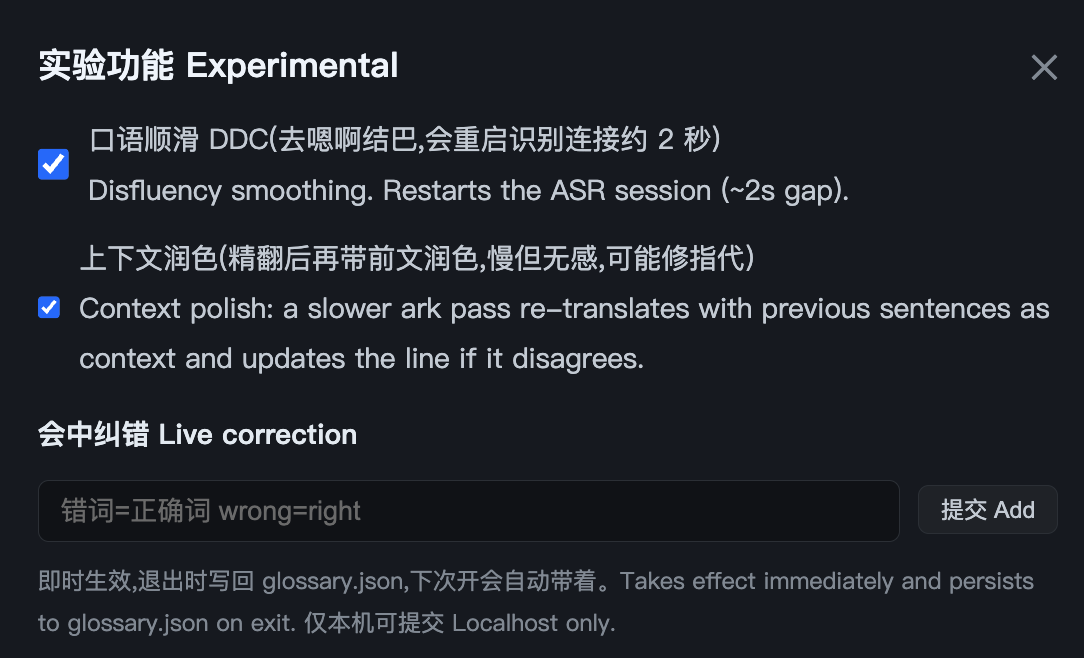
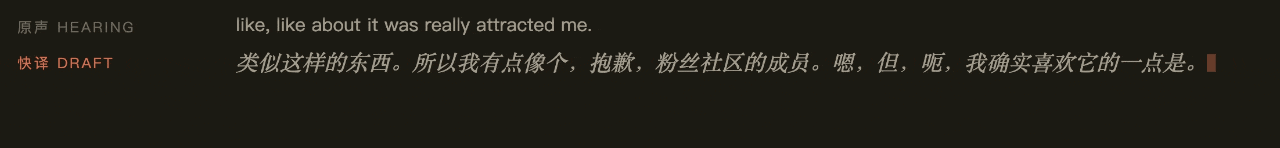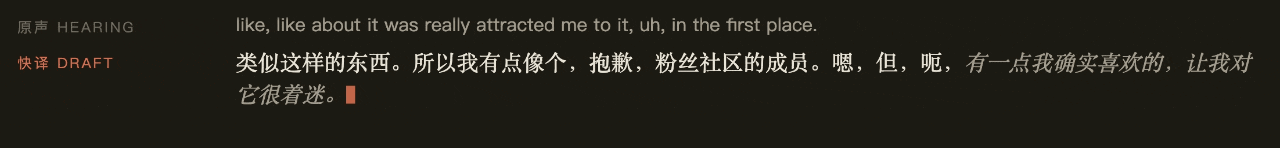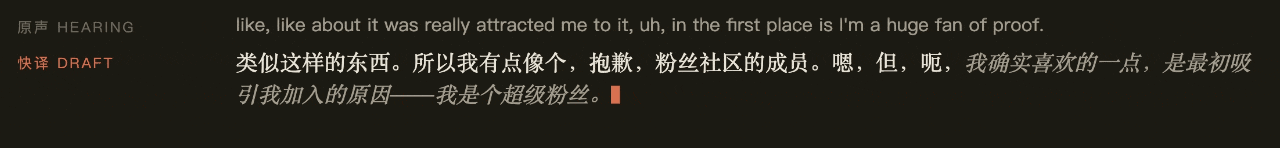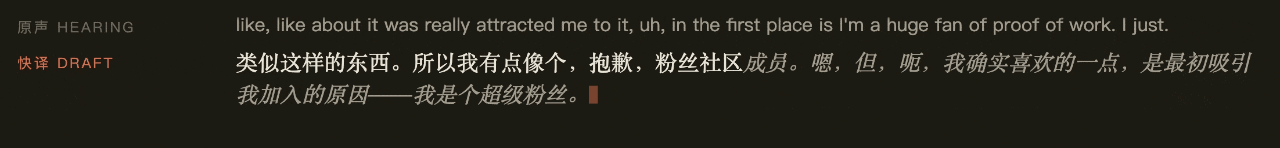
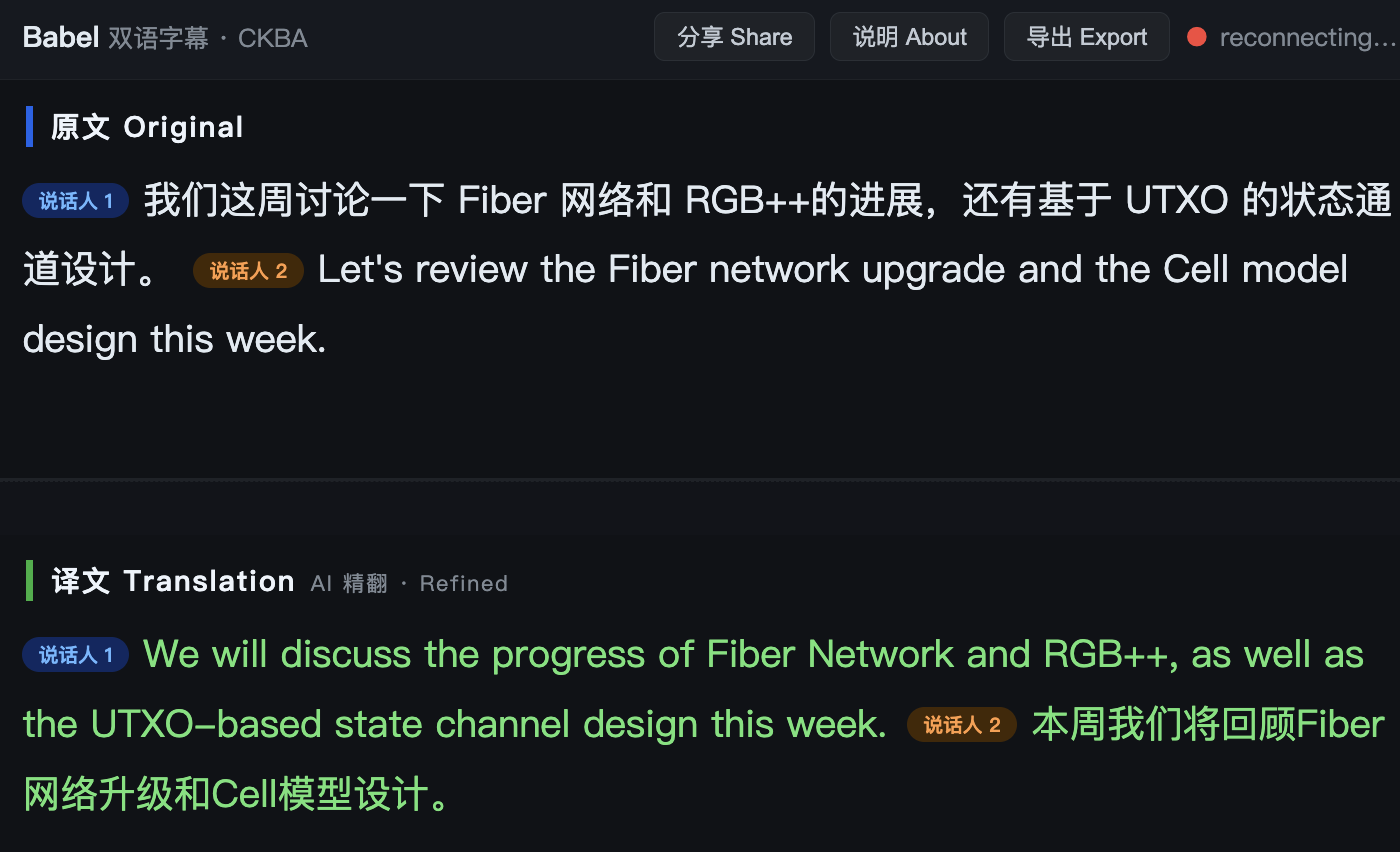
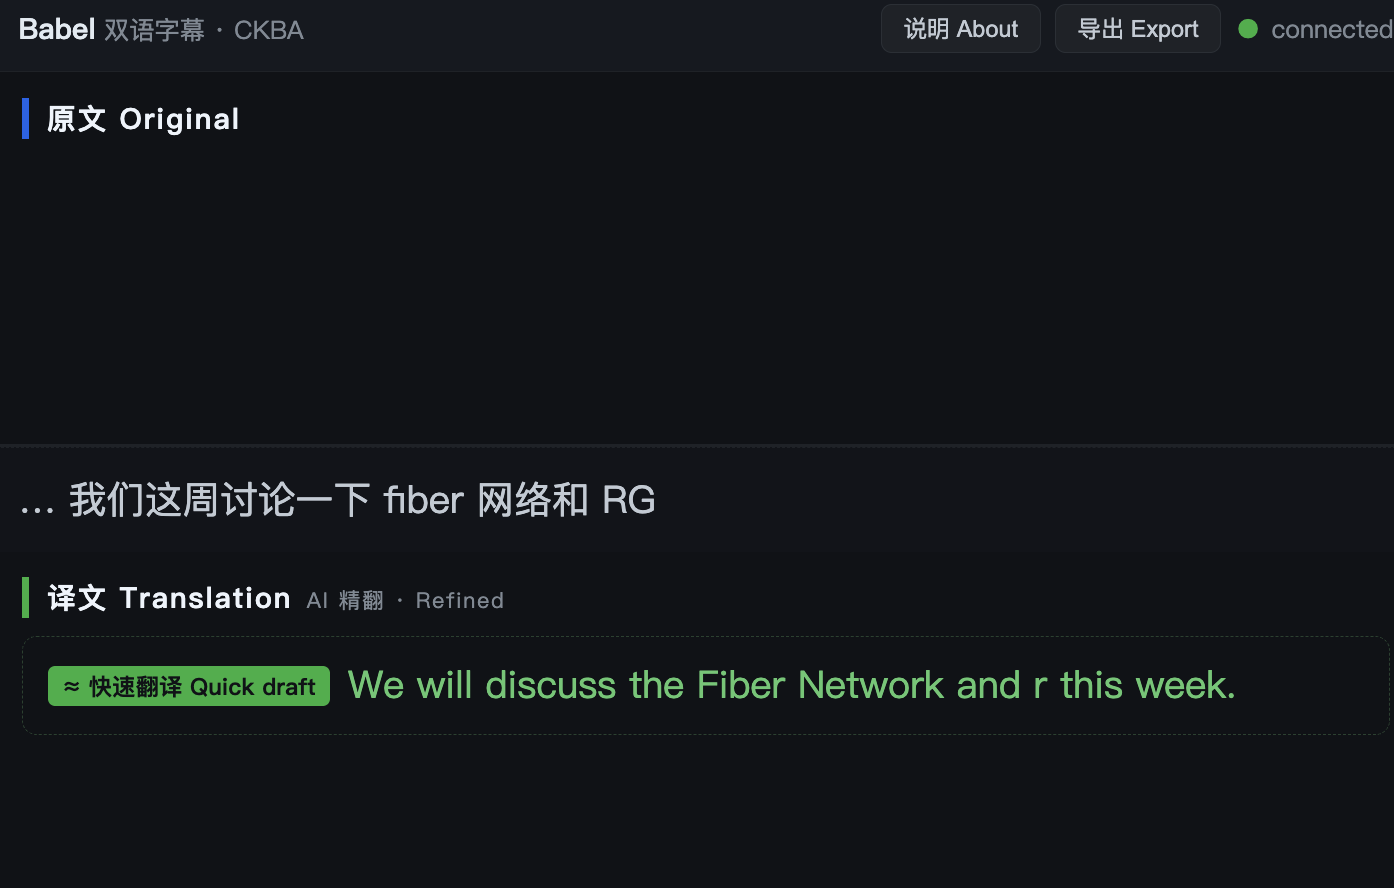
- Draft translation follows live speech (“≈” means Quick draft); the refined translation replaces it ~0.5s after each sentence commits.
- Server-side speaker clustering with colored speaker chips; a speaker change closes the current sentence.
- Sentence accumulator with language-boundary split, silence watchdog, and filler filtering — real speech never shatters into fragments.
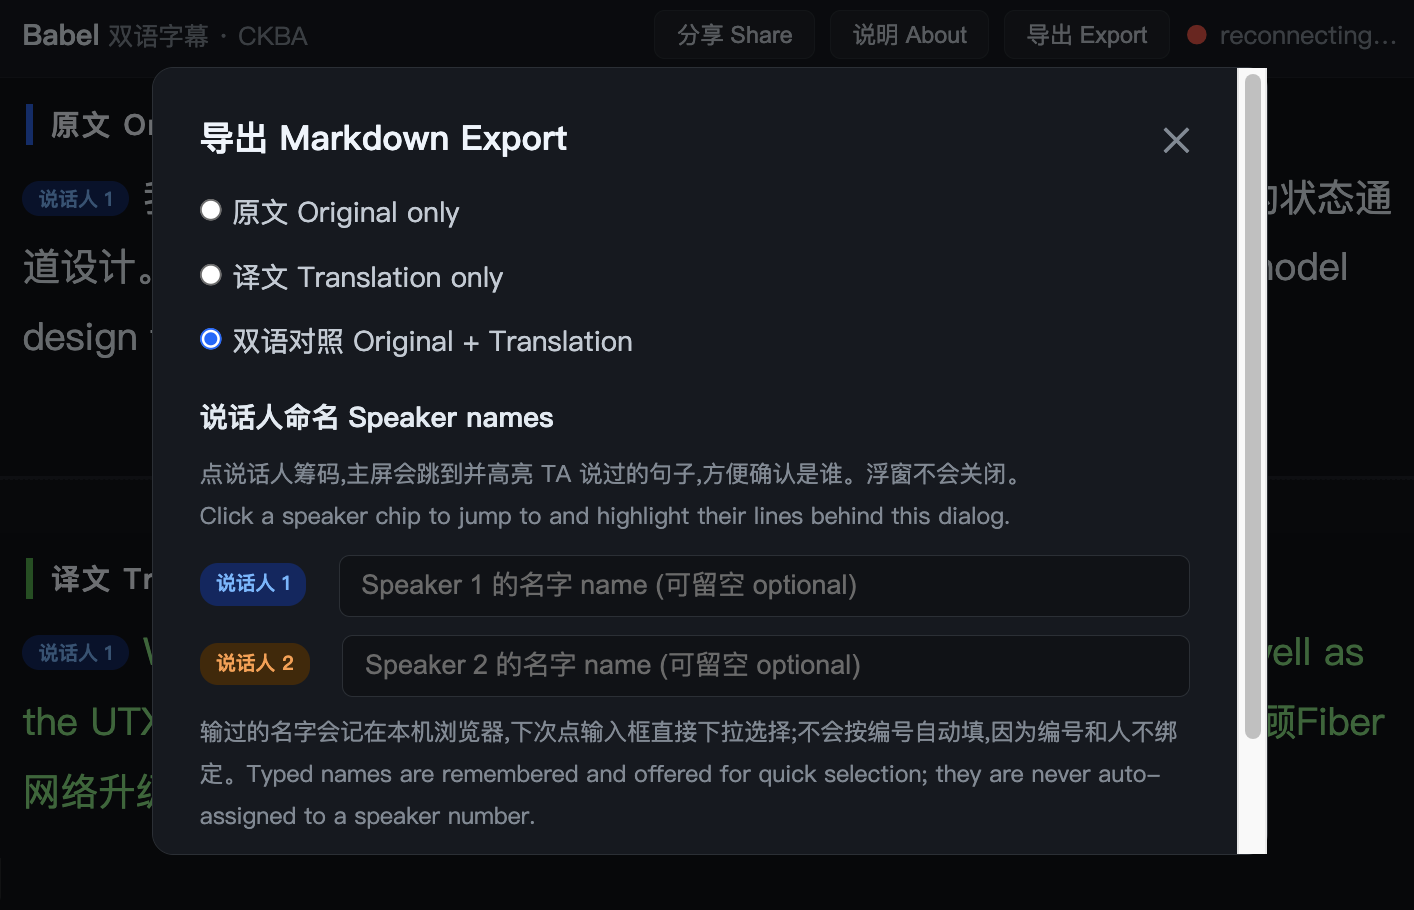
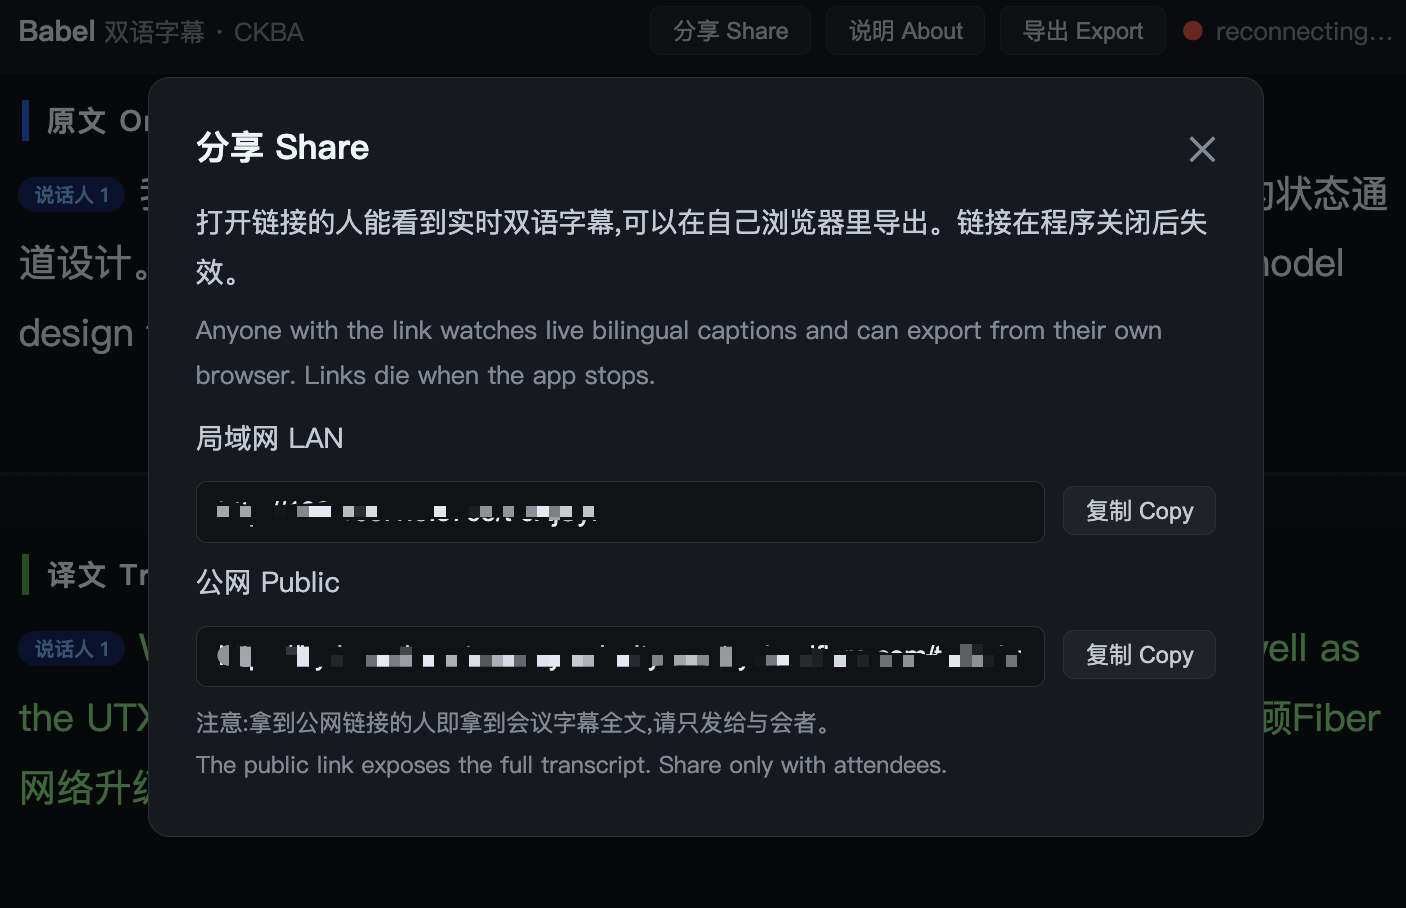
- One-flag sharing (LAN link, public cloudflared quick-tunnel link), in-page Markdown export (original / translation / bilingual, speaker names remembered locally).
- Domain adaptation without training: ASR hotwords (direct + self-learning boosting table), a client-side corrections map, a per-sentence translation glossary.
- One-click launcher (
Babel.command).
Repository layout
solution/— the app: Seed-ASR WebSocket client, translation backends, sentence accumulator, caption UI.hotwords/— CKB-community hotword lists (mined from the past year of Nervos Talk posts and public Nervos Telegram group chats) plus the generated boosting table.Babel.command— macOS double-click launcher (need to adjustDevicenumber).
Feel free to try it out and give any suggestions, thank you!